# Simon Spoorendonk
> Research-level output at startup velocity.
> Location: Copenhagen, Denmark. Contact: simon@spoorendonk.dk.
This file contains the complete content of the site in one document: profile, CV,
work, publications and full writing. A shorter index is at https://spoorendonk.dk/llms.txt and a
plain-text CV at https://spoorendonk.dk/cv.txt.
Last updated: 2026-10-01. Canonical URL: https://spoorendonk.dk/llms-full.txt
## Profile
- Name: Simon Spoorendonk
- Location: Copenhagen, Denmark
- Email: simon@spoorendonk.dk
- Currently: Research and open source at the intersection of classical optimization and modern AI: solver libraries, published research, and optimization systems built with AI coding agents.
- GitHub: https://github.com/spoorendonk
- LinkedIn: https://www.linkedin.com/in/spoorendonk/
- Google Scholar: https://scholar.google.dk/citations?user=Sy8INIQAAAAJ&hl=en
- ORCID: https://orcid.org/0009-0007-4304-6956
PhD computer scientist. Three-time founder in Copenhagen, two companies acquired. Twenty years of optimization and engineering — routing, scheduling, network flow. Friends with agents, fast-paced 0 → 1.
## Work
### Performance
#### Subset-row inequalities
Operations Research 56(2), 2008, 600+ citations
Closed 8 Solomon benchmark instances that had stood unsolved.
Cuts for the vehicle routing problem with time windows, with Mads Jepsen, Bjørn Petersen and David Pisinger. Each active cut adds a resource to the pricing problem, so a better bound is bought with a harder subproblem; the paper folds the cut contribution into the dominance criterion to make the trade pay. The cuts are now a standard component of state-of-the-art solvers.
https://doi.org/10.1287/opre.1070.0449
#### Parallel pull labelling
arXiv, 2025, revised 2026, with Bjørn Petersen
Around 18× over a baseline version of the same algorithm on hard instances, up to 274× at best, and 1.9–2.4× faster than an open implementation of the bucket-graph algorithm on the same hardware.
Classical labelling pushes labels forward, so parallel writes collide. Pulling instead — each bucket gathers the labels reaching it — parallelises cleanly at the bucket level, with a dynamic bidirectional midpoint and a vectorised dominance check.
https://doi.org/10.48550/arXiv.2511.01397
#### Bucket-graph labelling
arXiv, 2026, bucket-graph-spprc, C++23
1.3–2.35× faster than PathWyse, the main open-source comparator, in shifted geometric mean at an identical bound.
bucket-graph-spprc, a header-only C++23 library implementing the bucket-graph labelling algorithm of Sadykov, Uchoa and Pessoa — their algorithm, and the pricing algorithm behind VRPSolver. A compile-time resource concept means a new variant is one seven-function interface, with no runtime dispatch; rank-1 cuts ship as one of five built-in resources.
https://github.com/spoorendonk/bucket-graph-spprc
### Scale
#### Tree-based multi-commodity flow
arXiv, 2025, revised 2026, with Bjørn Petersen
Reverses a 1993 wall-clock conclusion at three orders of magnitude more scale: 1.4–1.9× faster on shifted geometric mean, 99× on the largest instance, solving 43–44 of 44 where the path-based formulation solves 38–42.
Jones et al. found in 1993 that path-based decomposition converged in fewer iterations and ran faster. The convergence result still holds; the wall-clock one does not, because the master problem is 87–99% of runtime and the tree-based master is up to 32 times smaller at termination. Iterations were the wrong thing to count.
https://doi.org/10.48550/arXiv.2509.24656
#### Routing in coso
Open source, 2026
A hybrid genetic search, in the manner of HGS-CVRP and PyVRP: no optimality proof, and instance sizes an exact method cannot reach at all.
Exact methods prove optimality, and that proof is expensive: it bounds the instance sizes reachable at all. This takes the opposite trade deliberately. For many real routing problems the proof is not worth its price. Knowing which trade a problem deserves is most of the work. coso is early development, the routing engine furthest along.
https://github.com/spoorendonk/coso
#### Capacitated profitable tour
arXiv, 2026
A component study on a fully open MIP stack, with every separator and all benchmark scripts released, isolating what actually helps.
A branch-and-cut solver for the capacitated profitable tour problem, where you choose which customers to serve as well as how to route them. The point of the paper is less the solver than the method: build it on an entirely open stack, release every separator and every script, and then take the pieces out one at a time to see which ones were carrying the result.
https://doi.org/10.48550/arXiv.2607.04497
#### Presolve heuristics for MIP
arXiv, 2026, mip-heuristics, inside HiGHS
Four published heuristics — FeasibilityJump, FPR, LocalMIP and Scylla — run at presolve inside HiGHS: a 23.7% better primal integral than unpatched HiGHS on 233 mipfeas instances, 12.9% on the ones not used for tuning.
Branch-and-bound finds the optimum eventually; under a time limit what matters is the incumbent when the clock stops. Presolve heuristics look for good feasible solutions before the search tree starts, using the solver’s own machinery rather than working around it.
https://github.com/spoorendonk/mip-heuristics
### Software
#### Flowty
Founder & CEO/CTO, 2019–2026
Scheduling delivered in production with the Ørsted team, with industry pilots at DHL, Svitzer and Unifeeder.
An optimization solver for planning and scheduling in logistics: multi-commodity flow, vehicle routing and resource-constrained shortest path, solved by branch-cut-and-price. Tech lead on the solver and its architecture; the master LP is solved with a GPU-accelerated PDLP and barrier hybrid.
https://flowty.ai
#### Research engineering
2026–present
Preprints on arXiv — new work, and earlier papers rewritten from the ground up — with the solvers and benchmark scripts released open source.
Working full time inside coding agents, implementing algorithms directly from research papers. Alongside the libraries above: mipx, a branch-and-cut MIP solver written from scratch; cbls, a constraint-based local search engine; and md2mip, which compiles a model written in prose into a standalone solver CLI.
### Method — Why any of this is checkable
Operations research has a property most of computing does not: you can prove a solution is optimal, and the instances everyone benchmarks on are public, with best known results anyone can look up. A claim is reproducible or it is not.
So the multi-commodity flow paper runs five LP backends spanning open-source and commercial, CPU and GPU, because a result that only holds under one solver is a property of that solver. It quantifies the mechanism rather than asserting it, publishes the counterexample where the method loses by a factor of eight along with the reason, and corrects a memory claim from the previous version, from up to 5x down to at most 2.86x with a geometric mean of 1.09x. The capacitated profitable tour study applies the same instinct to a whole solver: every separator and all benchmark scripts released on a fully open MIP stack.
This is also what makes working quickly defensible. The pace is a fact rather than a boast only because each result is measured against public instances at a stated bound, by anyone who cares to re-run it. Speed without verification just accumulates error faster.
## CV
Simon Spoorendonk
Research-level output at startup velocity.
Copenhagen, Denmark · simon@spoorendonk.dk
GitHub: https://github.com/spoorendonk
LinkedIn: https://www.linkedin.com/in/spoorendonk/
Google Scholar: https://scholar.google.dk/citations?user=Sy8INIQAAAAJ&hl=en
ORCID: https://orcid.org/0009-0007-4304-6956
Web: https://spoorendonk.dk/
Last updated: 2026-10-01. Canonical URL: https://spoorendonk.dk/cv.txt
PROFILE
-------
PhD computer scientist. Three-time founder in Copenhagen, two companies acquired. Twenty years of optimization and engineering — routing, scheduling, network flow.
Peer-reviewed publications in Operations Research, Transportation Science, EJOR and Networks, plus current preprints on arXiv. 1,500+ citations, h-index 15.
My work usually starts with someone talking about a problem they can’t solve. If that sounds familiar, write to me.
EXPERIENCE
----------
Research engineering (2026–present)
Optimization and modern AI: solver libraries, published research, and systems built with AI coding agents. Preprints on arXiv: new work, and earlier papers rewritten from the ground up.
Founder & CEO/CTO, Flowty (2019–2026)
Optimization solver for planning and scheduling in logistics. Tech lead on the solver and its architecture. Delivered in production with Ørsted; pilots with DHL, Svitzer and Unifeeder.
Co-Founder & CTO, Onlaw (2017–2018)
Legal research platform built on an NLP pipeline for semantic search over unstructured documents. Acquired by Karnov Group in 2020.
Co-Founder & CTO, Halfspace (2013–2018)
AI and data science consultancy for maritime, energy and insurance. Acquired by Accenture in 2025.
Software developer, Edlund A/S (2012–2013)
Actuarial software for pension and insurance, where correct and auditable results were the product.
Independent consultant, Freelance (2011–2019)
AI and decision-support projects for insurance, pension and asset allocation clients.
Postdoc, DTU (2009–2011)
Principal investigator on a DKK 1.5M grant from the Danish Council for Independent Research. Decomposition algorithms for transportation and scheduling, in collaboration with Maersk Line.
PhD student, University of Copenhagen (2005–2008)
Thesis: Cut and Column Generation.
Visiting PhD student, GERAD, Montréal (2007)
Resource-constrained shortest path algorithms with Guy Desaulniers and Jacques Desrosiers.
Software developer, WHO Regional Office for Europe (2001–2005)
Help desk assistant, WHO Regional Office for Europe (1999–2001)
ADVISORY AND TEACHING
---------------------
External examiner, Censorkorpset i Datalogi, Denmark (2026–present)
The national external examiner corps for computer science, covering the Danish universities.
Startup mentor, DTU Science Park (2025–present)
Coaching deep-tech founders on technology choices and scaling.
External examiner, DTU Management Engineering (2012–present)
External examiner for master's theses in operations research and optimization.
External lecturer, DTU Management Engineering (2013–2014)
EDUCATION
---------
PhD in Computer Science, University of Copenhagen (2008)
Thesis: Cut and Column Generation.
MSc in Computer Science, University of Copenhagen (2005)
SELECTED PUBLICATIONS
---------------------
Subset-row inequalities applied to the vehicle-routing problem with time windows
M. Jepsen, B. Petersen, S. Spoorendonk, D. Pisinger. Operations Research 56(2), 2008.
https://doi.org/10.1287/opre.1070.0449
A branch-and-cut algorithm for the symmetric two-echelon capacitated vehicle routing problem
M. Jepsen, S. Spoorendonk, S. Ropke. Transportation Science 47(1), 2013.
https://doi.org/10.1287/trsc.1110.0399
Liner shipping cargo allocation with repositioning of empty containers
B. D. Brouer, D. Pisinger, S. Spoorendonk. INFOR 49(2), 2011.
https://doi.org/10.3138/infor.49.2.109
A hybrid adaptive large neighborhood search heuristic for lot-sizing with setup times
L. F. Muller, S. Spoorendonk, D. Pisinger. European Journal of Operational Research 218(3), 2012.
https://doi.org/10.1016/j.ejor.2011.11.036
Cutting planes for branch-and-price algorithms
G. Desaulniers, J. Desrosiers, S. Spoorendonk. Networks 58(4), 2011.
https://doi.org/10.1002/net.20471
A branch-and-cut algorithm for the capacitated profitable tour problem
M. K. Jepsen, B. Petersen, S. Spoorendonk, D. Pisinger. Discrete Optimization 14, 2014.
https://doi.org/10.1016/j.disopt.2014.08.001
PREPRINTS
---------
Presolve heuristics in HiGHS: implementation and computational study
S. Spoorendonk. arXiv:2609.22938, 2026.
https://arxiv.org/abs/2609.22938
An open, reproducible branch-and-cut for the capacitated profitable tour problem: a component study
S. Spoorendonk. arXiv:2607.04497, 2026.
https://arxiv.org/abs/2607.04497
bucket-graph-spprc: an extensible C++ library for the shortest path problem with resource constraints
S. Spoorendonk. arXiv:2606.30847, 2026.
https://arxiv.org/abs/2606.30847
A parallel pull labelling algorithm for the resource constrained shortest path problem
B. Petersen, S. Spoorendonk. arXiv:2511.01397, 2025, revised 2026.
https://arxiv.org/abs/2511.01397
Tree-based formulation for the multi-commodity flow problem
S. Spoorendonk, B. Petersen. arXiv:2509.24656, 2025, revised 2026.
https://arxiv.org/abs/2509.24656
OPEN SOURCE
-----------
bucket-graph-spprc — Header-only C++23 bucket graph labeling for the SPPRC — the pricing subproblem in vehicle routing column generation.
https://github.com/spoorendonk/bucket-graph-spprc
cptp — Branch-and-cut solver for the Capacitated Profitable Tour Problem (CPTP) and open s–t path variants.
https://github.com/spoorendonk/cptp
coso — Typed model API + C++23 structure-aware engine for routing, scheduling, assignment, packing, network flow, lot sizing (early development).
https://github.com/spoorendonk/coso
mcfcg — Column generation for minimum-cost multicommodity flow with path- and tree-based Dantzig-Wolfe decompositions.
https://github.com/spoorendonk/mcfcg
mip-heuristics — Four MIP presolve heuristics (FeasibilityJump, FPR, LocalMIP, Scylla) implemented and benchmarked inside HiGHS.
https://github.com/spoorendonk/mip-heuristics
cbls — Constraint-based local search (ViolationLS) for mixed discrete-continuous optimization — C++23 with Python bindings.
https://github.com/spoorendonk/cbls
mipx — A from-scratch branch-and-cut MIP solver in C++23 with Python bindings (early development).
https://github.com/spoorendonk/mipx
md2mip — Compile natural-language optimization models into standalone solver CLIs (Python + HiGHS).
https://github.com/spoorendonk/md2mip
## Writing
### How I check agent-built solvers
2026-10-01 · https://spoorendonk.dk/writing/how-i-check-agent-built-solvers
Nobody reads all the code any more, and I don't either.
What I care about is keeping an agent from handing me an algorithm, a solver or
a paper that looks right and isn't.
My examples are from building optimization algorithms. I think most of it
carries over to other code that implements a published method and produces
numbers.
This is how I work as of autumn 2026. I started building with coding agents in
February 2026, and it took off properly in April. I focused on a specific kind of project: one or a few papers turned
into a new code base, run through experiments, and written up. Greenfield code,
no users to keep happy, and not necessarily novel research. Some of it is
reimplementation, some is engineering, and the paper should say which is which.
[mip-heuristics](https://github.com/spoorendonk/mip-heuristics), for example,
puts four published heuristics inside one solver so they can be compared like
for like. That's a benchmark, not a new method.
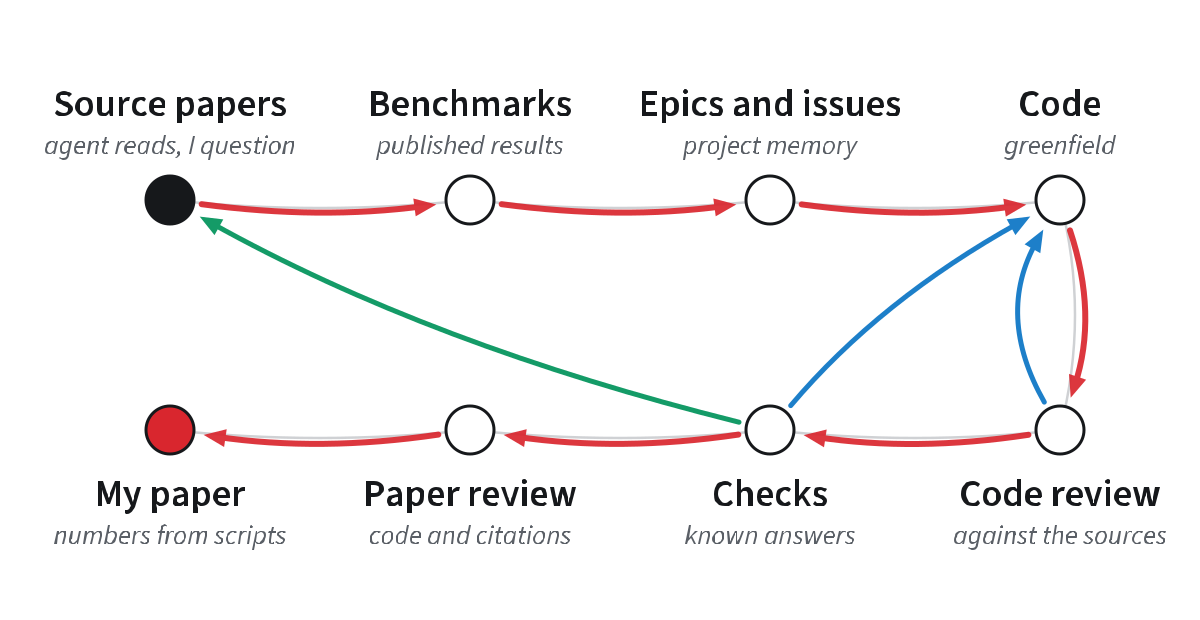
How a project runs, from other people's papers to mine. Red is the
main flow. Blue arrows go back to the code when a review or a check fails. The
green arrow goes back to the source papers, when the code doesn't behave the
way a paper says it should. Before my paper goes out, it's reviewed against the
code and its citations against the papers they cite.
## Reading the papers
I don't read every paper either, and certainly not when the trail goes back
twenty years. The agent reads them. What I do is cross-examine it. What does
this paper do, how is it different from the one before, is that in the
paper or did you infer it. I keep asking until the answers stop moving. Having
read a lot of papers in my earlier days helps with knowing what to ask.
It doesn't catch everything. Discrepancies still turn up later, usually when
something is implemented and doesn't behave the way the paper says it should.
## What do we compare against?
Before planning any code I decide how I'll validate it. The best case is an
answer to compare against, and I prefer answers that are published or that I
can reproduce, such as known optima on public instances. Results from old
papers work too, the
solution values rather than the run times, since the machines are long gone.
So does other people's published code, if it runs.
When there's no reference solution at all, the ablations have to carry more of
the weight. An ablation switches components off one at a time to see what each
one is worth. Ablations can't tell you the answer is right, but they can tell you
sensible things about each part of the algorithm and whether it does what it's
supposed to.
## Epics, issues and docs
I track the work in GitHub epics: development, experiments, and writing the
paper. The experiments split in two. The headline runs are usually given up
front, since the point is speed or solution quality on benchmarks everyone
already uses. Ablations are harder to plan, and they drift as I understand the
code better. That's fine as long as the drift is written down.
Under the epics, the agents write issues to themselves. I rarely read them, but
we talk about them, and they're the project's memory. Anything decided, found
or postponed ends up in one.
The docs in the repo take more effort than you'd think. Agents write a lot of
documentation, and most of it is too long. Keeping it short and to the point is
work I have to ask for, again and again.
## Did we build the algorithm in the paper?
Most of the review rounds go on this. The point is to make sure the code
implements the algorithm the paper states, all of it, and that nothing was
left out because the agent postponed it or decided it wasn't needed. The code
should only differ from the paper where the paper is unclear, where we found a
better way, or where the authors' own code does something different and we
follow it. Either way it gets written down, and a change like that usually
needs its own tests.
On mip-heuristics the review found many defects across the four heuristics it
implements. In one, the relaxed solution the method is built around never
reached the rounding step. In another, what shipped was the variant the paper
itself abandons. It also turned up two bugs in Feasibility Jump inside
[HiGHS](https://github.com/ERGO-Code/HiGHS). Both came in with the reference implementation. The
objective was counted with the wrong sign, so it steered towards worse
solutions, and when working out where to move a variable, rows where it has a
negative coefficient were skipped.
Nothing in the benchmark results pointed at any of them. A heuristic running
the wrong variant still runs, and still finds solutions some of the time.
Reading the code against the paper is what found them.
Alongside that there are regular reviews of the architecture and the
performance, like any project should have.
## Checks on the numbers
For bugs where the answer comes out wrong, the checks are the usual ones. Tiny
instances you can enumerate. The reference answers from before any code
existed. The same problem through someone else's solver on the same machine. Unit tests catch the
mechanical stuff. Ablations are about which component carries the result, but
because they mean running a lot, they turn up the odd bug as well.
Bugs in my own logic are cheap. These checks find them, and they're quick to
fix because the whole code base is right there. The expensive ones are in code
I didn't write. In [mcfcg](https://github.com/spoorendonk/mcfcg), NVIDIA's GPU
solver [cuOpt](https://github.com/NVIDIA/cuopt) once handed back a cost about 170
times too high, sometimes labelled solved, after a linear algebra step failed
underneath it. I fixed that one in my own fork. HiGHS's new interior-point
solver threw away a near-optimal solution and reported an internal error. In
both cases it took another solver on the same model to see what had gone
wrong.
## Writing the paper
This is where a lot of my own time goes.
The algorithms in the paper are written the way they're implemented, and where
they've changed from a previously published version, the paper says so.
Citations get checked twice. The agent follows each DOI to check the reference
exists and says what we think it says, and then there's whether the person
cited did what we cite them for. I'm nitpicky about that one,
especially in the literature overview. Giving the right people credit matters.
No number is typed from memory. In the
[multi-commodity flow paper](https://arxiv.org/abs/2509.24656) the tables are
generated by script from the result files. A second script holds a copy of
every number in the prose that comes from our runs, re-derives each one from
the data, and fails if they disagree. The checker
has had bugs too. It once let a 1.94 through where the table said 1.93.
And I try hard not to overclaim. A result goes in with the conditions it holds
under and where it loses.
## Same as always, just faster
None of this is new. It's the project, software and research practice that good
work always needed: decide how you'll validate, check the code does
what the paper says, don't trust a number nobody derived, and credit people
properly.
What's changed is the speed. The work goes a lot faster, but these algorithms
are still hard to implement, and an agent will hand you something that looks
finished long before it is.
That's where things are now.
---
### Pull instead of push
2026-09-08 · https://spoorendonk.dk/writing/pull-instead-of-push
This is joint work with Bjørn Petersen.
Almost every large routing or scheduling solver has the same shape. There is an
outer loop that keeps track of the overall plan, and an inner loop that repeatedly
answers one narrow question: *given the current prices, what is the best single
route I could add?*
The inner question is a shortest path problem carrying baggage. The route has to
respect a vehicle's capacity, its shift length, delivery time windows, which stops
can legally follow which. Formally it is the shortest path problem with resource
constraints, and in a working solver it is where nearly all the time goes.
Which is good news, in a way. When one loop dominates the runtime, you know exactly
where to stand, though it is worth checking which loop, because in other
decompositions the bottleneck sits in the master problem instead.
## How the loop normally works
The standard method builds partial routes and extends them one stop at a time. A
partial route is called a *label*: where it is, what it cost, how much capacity is
used, what time it is.
Two things happen constantly. **Extension:** take a label, add a legal next stop,
make a new label. **Dominance:** if route X is at the same place as route Y, and
is no worse on every single measure, cost and time and remaining capacity, then Y
can never lead anywhere X can't. Throw Y away.
Dominance is what keeps this from exploding. It is also the hot loop inside the
hot loop: constant comparison of every new label against the ones already there.
## Why parallelising it is awkward
The obvious move is to use more cores. The obvious approach fails in an
interesting way.
Classical labelling **pushes**: take a label, generate its extensions, and write
each one into wherever it lands. With many threads pushing at once, they write
into the same places simultaneously. Now you need locks, or lock-free structures,
and you spend your parallelism defending the data instead of doing work.
The problem is not the computation. It is the direction of the writes.
## Turning it around
So don't push. **Pull.**
Group the labels into buckets by location and by roughly how much resource is used.
Then, instead of each label pushing its extensions outward, each bucket goes and
*gathers* the labels that would reach it.
The arithmetic is identical. But now every bucket writes only to itself. A thread
that owns a bucket owns it completely, so workers never have to coordinate access
to a bucket at all: no collisions and no locks on the buckets themselves. What is
left to synchronise is global rather than structural, the best bound found so far
and the pool of finished paths, one lightweight lock each.
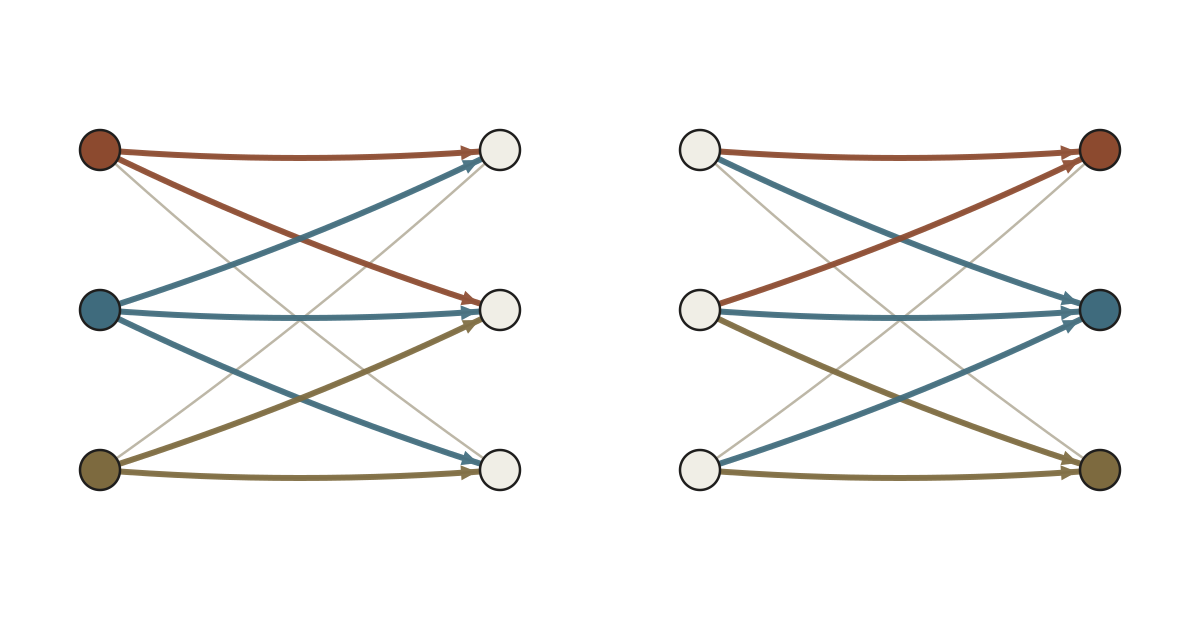
The same extensions in both panels, flowing the same way. Filled
circles are the ones doing the writing. On the left every label writes into
whichever bucket it lands in, so three threads write into the middle bucket at
once. On the right every bucket gathers what reaches it, so each bucket is
written by one thread only.
Two things stack on top. **Bidirectional search** builds routes from both ends and
meets in the middle. That is much less work, because the search grows sharply with
depth, and we let the meeting point move as the search learns where the real cost
lies rather than fixing it up front. And because a bucket's labels now sit
together in memory, the dominance comparison can be **vectorised**: the CPU checks
several labels against a candidate in one instruction instead of one at a time.
## What it was worth
There are two numbers, and they answer two different questions.
The first is an ablation. The baseline is the same algorithm with none of the
three ideas switched on: one thread, one direction, dominance checked one label
at a time. Against that, on the same instances and on one 16-core desktop, the
full version is **around 18× faster on hard instances, and up to 274× on the
instance that gains most.** That figure includes the parallelism itself rather
than isolating it, which is the honest way to read it: reorganising the loop is
what made the parallelism available in the first place, so the two are not
separable.
The spread matters more than the headline. The gain is largest exactly where the
instances are worst: where labels pile up, where dominance is doing the most work,
where the old approach was struggling most. That is the useful shape for a
speed-up to have. A method that is fast on easy problems and slow on hard ones has
not helped with anything; your easy problems were already fine.
The second is against a competitor.
[bucket-graph-spprc](https://github.com/spoorendonk/bucket-graph-spprc) is our
open implementation of the state-of-the-art bucket-graph algorithm of Sadykov,
Uchoa and Pessoa. Being a push algorithm, it parallelises the two search
directions and its internal sorting, but not the buckets, for exactly the reason
above: extending one bucket writes into several successor buckets that other
threads are also writing. Run on that same machine and those same instances,
each solver in its own best parallel configuration, pull is 1.9 to 2.4 times
faster, and faster on 164 of the 168 instances.
So the fair statement is not that pull uses more threads. It is that pull can put
its threads somewhere push cannot.
## What it costs
The ordering that makes this safe is not free, and it is worth being plain about
where the bill lands.
A bucket can only be gathered once every bucket that feeds it is finished, so the
buckets have to be sized small enough that those dependencies never form a cycle.
That forces the bucket size down to the smallest resource consumption on any arc
touching the vertex, which is the largest size for which acyclicity still holds.
Sadykov and co-authors do not pay this, because a push algorithm can tolerate
small cycles.
Finer buckets mean more of them, longer chains of dependency between them, and
fewer labels sitting in each one for the vector unit to work on. And the amount
of parallelism actually available is bounded by the longest chain of dependent
work in the graph, however many cores you own. On the hardest instances, the ones
with large neighbourhoods, that restriction bites: parallelism is limited and the
worst case has a heavier tail. Allowing bounded cycles is the obvious next move
and the one we would most like to make, but it threatens the immutability the
whole scheme is built on.
## The general shape
None of this is a new algorithm. It is the same computation, reorganised so that
the machine underneath can actually do it in parallel, and modern machines punish
you hard for getting that wrong. The number of cores has grown far faster than the
speed of any one of them.
The move, *stop handing work out and start letting workers come and take it*, is
not specific to routing. It shows up wherever many producers write into shared
state. Whenever a parallel implementation is disappointing, it is worth asking
whether the work is being pushed when it could be pulled.
The paper is [arXiv:2511.01397](https://arxiv.org/abs/2511.01397).
---
### The 1993 answer was right until it wasn’t
2026-09-08 · https://spoorendonk.dk/writing/the-1993-answer-was-right-until-it-wasnt
If you ship things, or move electricity, or route data, you eventually meet the
multi-commodity flow problem. You have a network with limited capacity on each
link, and a long list of things that need to get from somewhere to somewhere
else. Everything competes for the same capacity. Find the cheapest way to
satisfy all of it at once.
The problem is old and well understood. What is less well understood is that
there is more than one way to write it down, and the choice matters enormously.
## Two ways to describe the same thing
You can describe a solution as **a set of paths**: this shipment goes A→C→F,
that one goes B→C→G. Natural, and it is how most people would sketch it on a
whiteboard.
Or you can describe it as **a set of trees**: everything leaving source A,
considered together, forms a shortest-path tree fanning out across the network.
Instead of one description per shipment, you get one per *origin*.
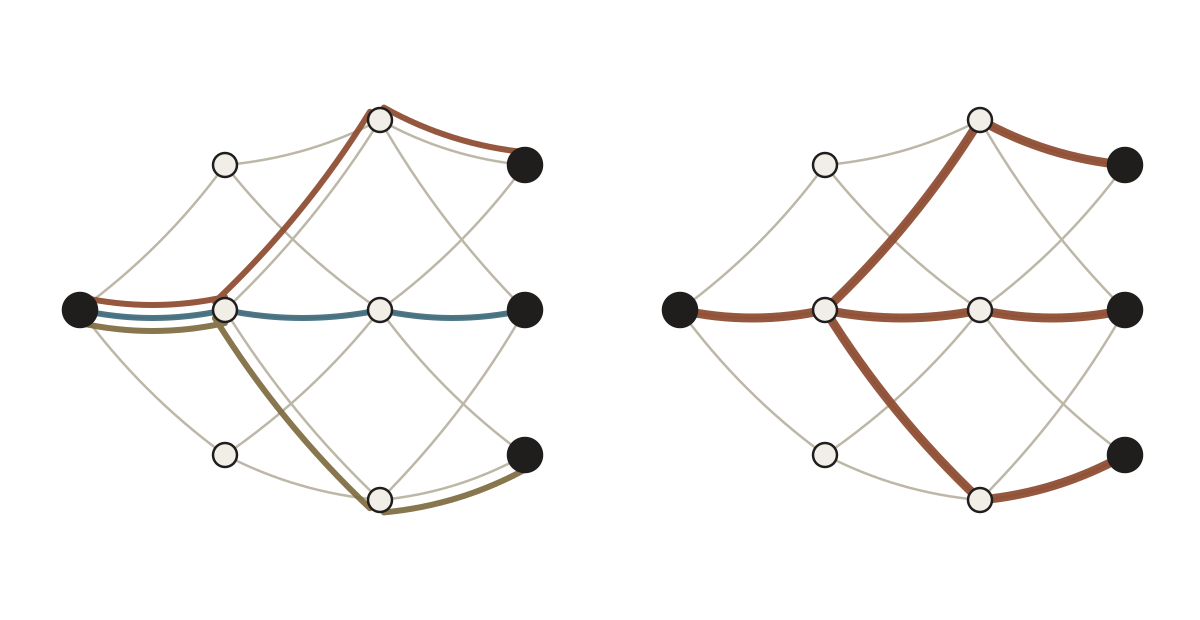
The same three shipments leaving one origin. On the left, one path
each, so the leg they share gets described three times over. On the right, one
tree, described once.
That distinction sounds academic until you count. A logistics network might have
a few hundred origins and several million individual shipments. The path-based
description needs a row in its bookkeeping for every shipment. The tree-based one
needs a row for every origin. Same problem, same answers, wildly different
amounts of paper.
## Why the question was closed
In 1993, Jones, Lustig, Farvolden and Powell compared the two properly. They
found the path-based version converged in fewer rounds *and* finished faster in
wall-clock time. Fewer rounds and less time is not a close call. The question was
settled, and the answer was inherited by everyone downstream for thirty-two years.
Their measurement was correct. I want to be clear about that, because the
interesting part is not that they were wrong.
## What changed
We re-ran the comparison on 44 instances, the largest with 3.3 million
commodities, about a thousand times the scale available in 1993.
The convergence finding held up exactly. The tree-based formulation still needs
two to three times as many rounds. If you count rounds, 1993 is still right.
The wall-clock finding reversed under every solver we tried: five different
linear-programming backends, open-source and commercial, CPU and GPU. Tree-based
came out 1.4 to 1.9 times faster on average, and 99 times faster on the largest
instance. It also finished 43 or 44 of the 44 instances, where path-based managed
38 to 42, and its failures clustered exactly where you would least want them, on
the biggest problems.
## Why, and why it took thirty-two years
Measurement tells you what happened; it does not tell you why. So we measured the
inside too.
The master problem, the bookkeeping step that reconciles everything, turned out
to be 87 to 99 percent of the total runtime on three of our four instance
families. Almost nothing else matters there. And the tree-based master is up to
32 times smaller at the point it finishes.
The fourth family is the exception that says what the mechanism is. On the
intermodal instances the master is a fifth of the runtime or less, sometimes one
percent, and the pricing step is where the time goes. Those instances have one
commodity per source, so a tree is a path, the tree-based master has exactly the
same number of rows as the path-based one, and there is nothing to compress.
They neither gain nor lose.
So the tree-based method takes more rounds, but each round is against a far
smaller object. In 1993, at the scale then reachable, the extra rounds dominated.
At three orders of magnitude more scale, the size of the thing you carry through
each round dominates instead. The crossover was always there. Nobody had a
machine big enough to walk past it.
**Iterations were the wrong thing to count.** They were a reasonable proxy for
time when the objects were small, and they stopped being one when the objects
grew.
## The case where it loses
We also published the case where our method loses. On one instance,
`planar2500`, where the number of origins approaches the number of nodes, the
tree-based version is eight times *slower*, and for a comprehensible reason: a
tree column then touches most of the master's rows, so the smallness that made it
fast is gone.
Publishing the counterexample is not modesty. It is the thing that makes the rest
of the numbers worth believing. It also tells you exactly when to use this and
when not to, which is what anyone deciding whether to adopt it actually needs.
## An objection
After the paper went out, it was pointed out to me that there is an approximation
scheme for this, and that it is much faster. Read the congestion off the edges,
update the edge costs from it, reroute by shortest paths, repeat. There is no master problem in it at all, which is not
a trick: it is simply a different method, and nothing is being reconciled
centrally, so there is nothing for a master problem to do.
What it gives up is exactness. Column generation returns an optimum with valid
dual values. An approximation scheme returns something within a tolerance you
choose. At the sizes where any of this matters, that is very often a trade worth
making, and I would not claim otherwise.
## The part I would want a reader to keep
Older results are not wrong so much as *scoped*. The scope is usually invisible,
because it lives in the hardware available when the measurement was taken. It is
worth asking, occasionally, which of the things you know were settled on machines
a thousand times smaller than the one on your desk.
The paper is [arXiv:2509.24656](https://arxiv.org/abs/2509.24656), with Bjørn
Petersen, and the implementation is at
[mcfcg](https://github.com/spoorendonk/mcfcg).